Repair PDF
Re-save and normalize a PDF's internal structure. This can recover files that open with minor errors — but it cannot rebuild severely corrupted files.
Choose files
or drag and drop them here
What PDF repair really does here, and what it can honestly recover
Repair PDF performs a structural re-save. The tool reads through the file object by object with the pdf-lib library, then writes everything it found into a new file with a fresh, correct index (the cross-reference table and trailer that PDF readers use to find each page). The new copy is saved as Repaired_ followed by your original file name. This helps when a PDF is "broken" because its index is wrong or missing, while the pages themselves are still in the file.
That kind of damage usually comes from a write that never finished: a download that stopped just before the end, an app that crashed while saving, or a copy to a USB stick that was cut short. We tested this with a copy of our 4-page sample report whose index, trailer and end-of-file marker had been cut off. PDF.js, the PDF engine used by Firefox, refused to open it with "Invalid PDF structure". After repair, the Repaired_ copy opened with all 4 pages rendering exactly like the undamaged original.
The limits are just as clear from testing. A copy cut off halfway through, which lost half of the actual page content, could not be repaired, and neither could a text file renamed to .pdf; in both cases the tool shows an alert saying the PDF couldn't be parsed, instead of producing a file that pretends to be fixed. A file whose index numbers were all wrong opened in PDF.js even before repair, because many readers fix that kind of problem themselves; the tool still produced a clean copy. Repair cannot recreate missing or overwritten data, and it does not remove passwords.
How to repair a corrupted PDF, step by step
The whole attempt takes one upload and one click, and you get a clear result either way.
- 1
Open the Repair PDF tool
Go to pdf.rupix.io/repair in any modern browser. No account or installation is needed, and the damaged document stays on your device for the whole process.
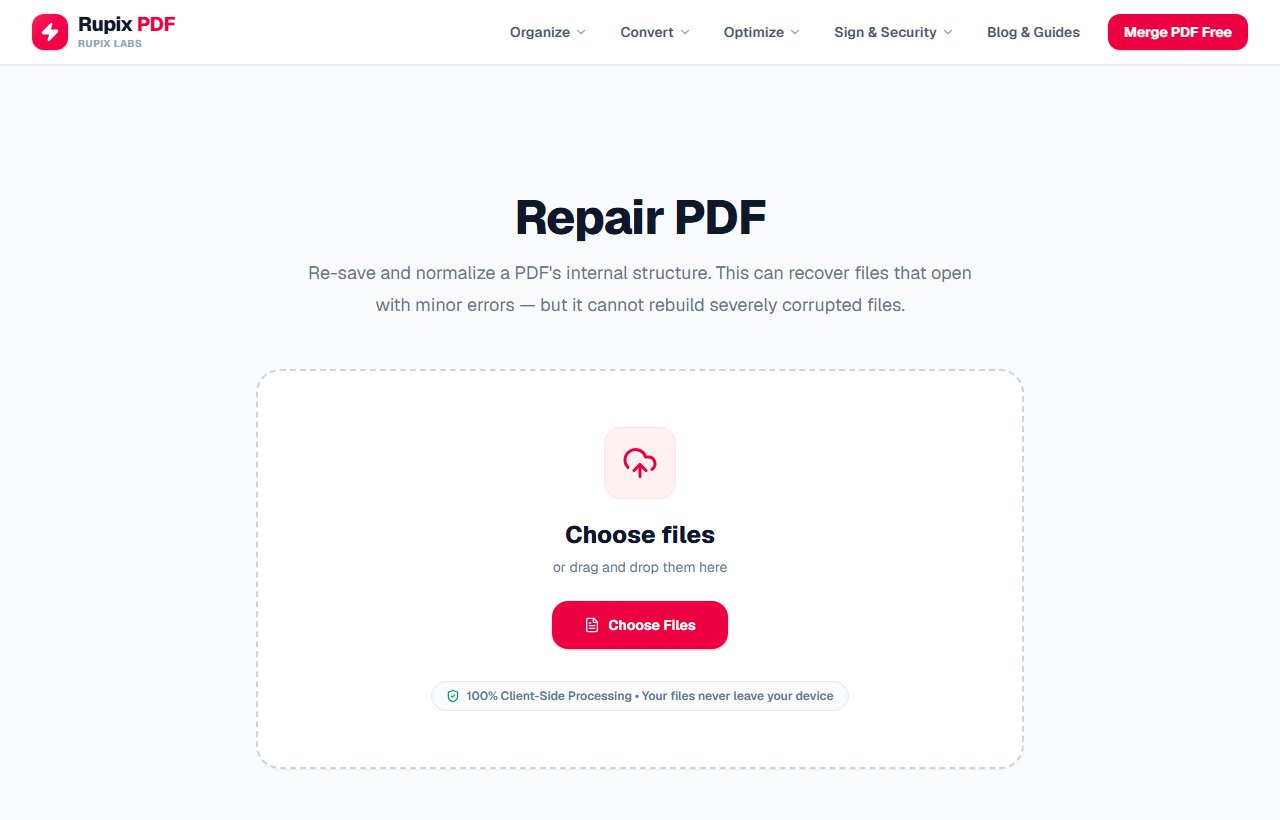
The Repair PDF page with its upload panel and Choose Files button. - 2
Add the damaged file
Click Choose Files and pick the problem PDF, up to 100 MB, or drag it onto the panel. A card shows the file's name and size above a Structural Re-save note and the Repair Document button. Click the X on the card if you picked the wrong file.
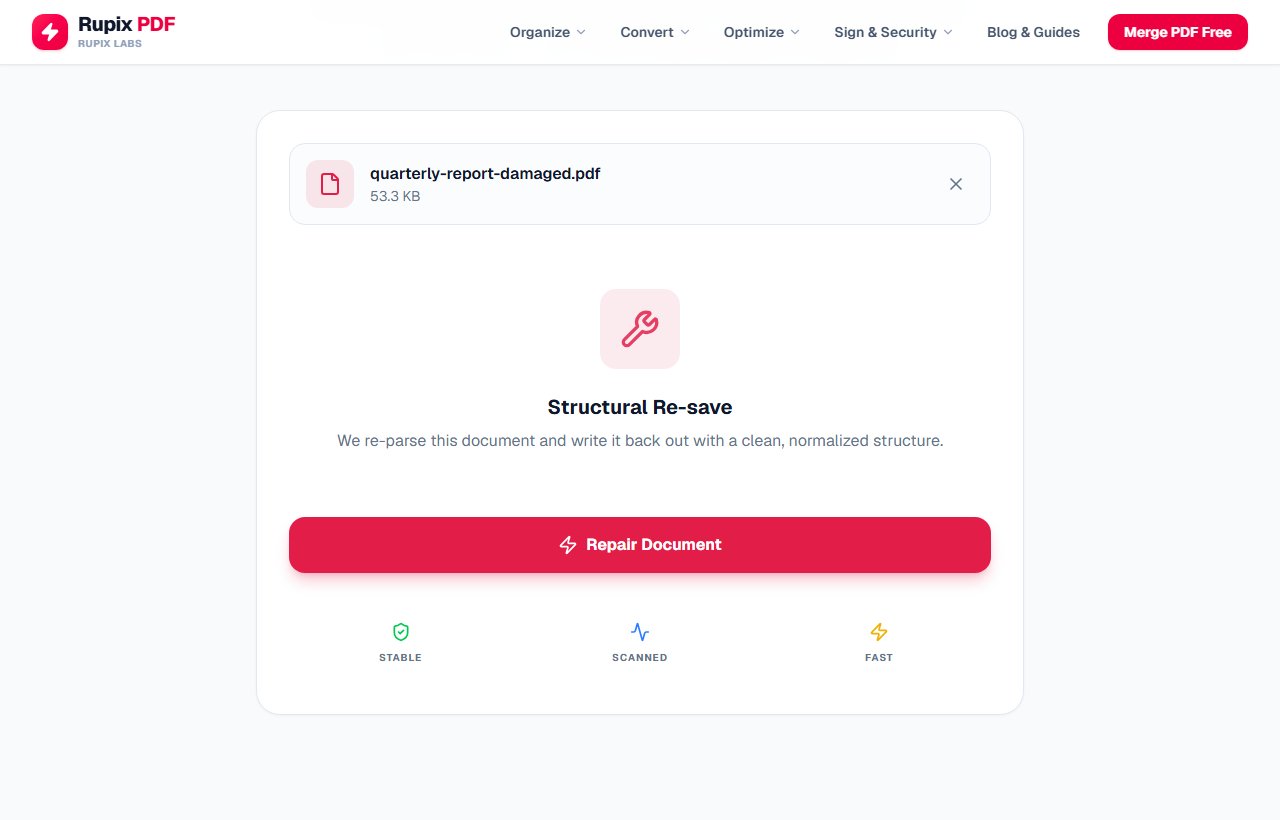
quarterly-report-damaged.pdf (53.3 KB) loaded, with the Structural Re-save note and the Repair Document button. - 3
Click Repair Document
Click Repair Document. The button changes to Reconstructing… and a small log lists each stage as it happens, with what was found: the file size read, the number of pages and objects parsed, and the size of the rewritten file. The bar above the log moves forward only when a stage finishes. Small files finish in a moment, so you may barely see this screen.
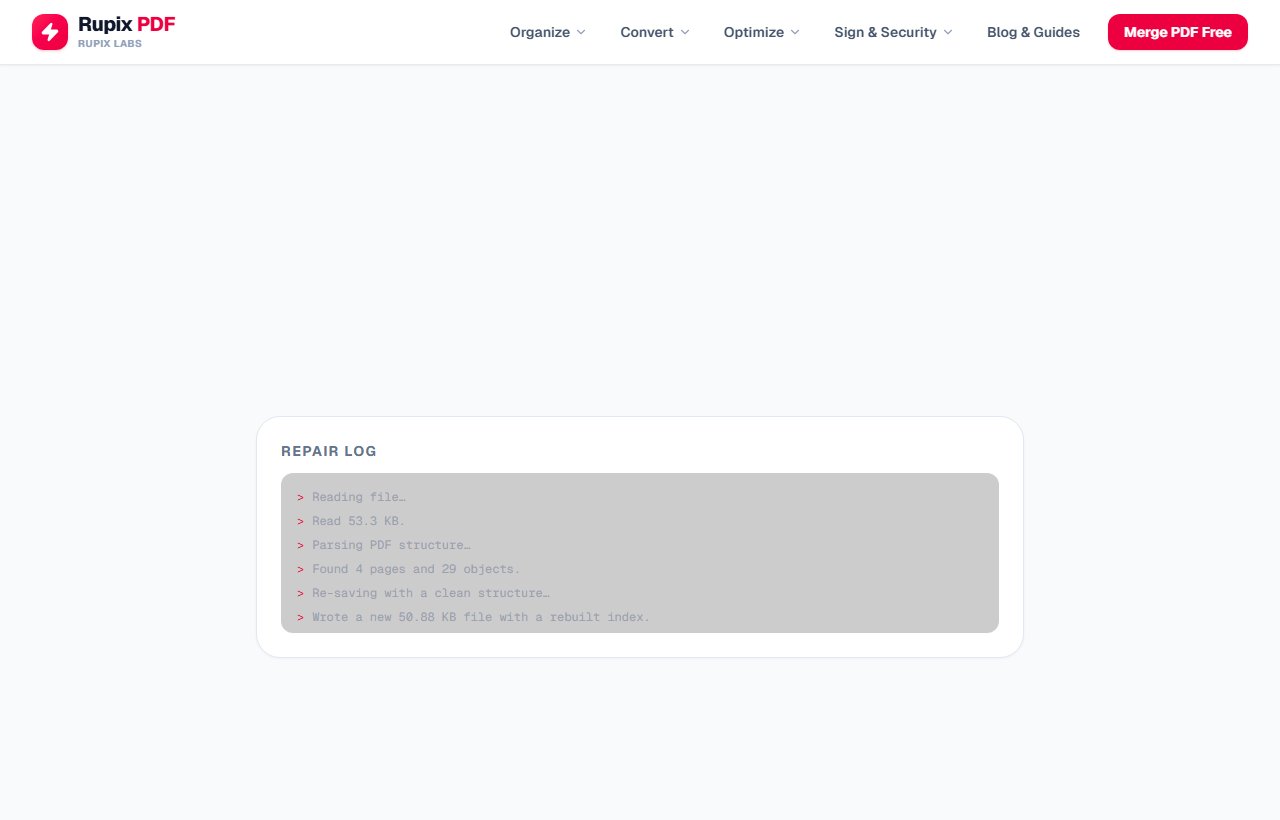
A larger damaged demo file (annual-report-damaged.pdf, 1.54 MB) being repaired, with the progress bar part-way, the log lines so far and the Reconstructing… button. - 4
Download the repaired copy
If the file could be read, the repaired copy downloads automatically as Repaired_ followed by the original name, and a PDF Re-saved! screen appears with the full repair log underneath, ending in Done — document re-saved. For our damaged 4-page report, the log reported 4 pages and 29 objects and a new 50.88 KB file. Use Download File if the download did not start. Your damaged original is not changed.
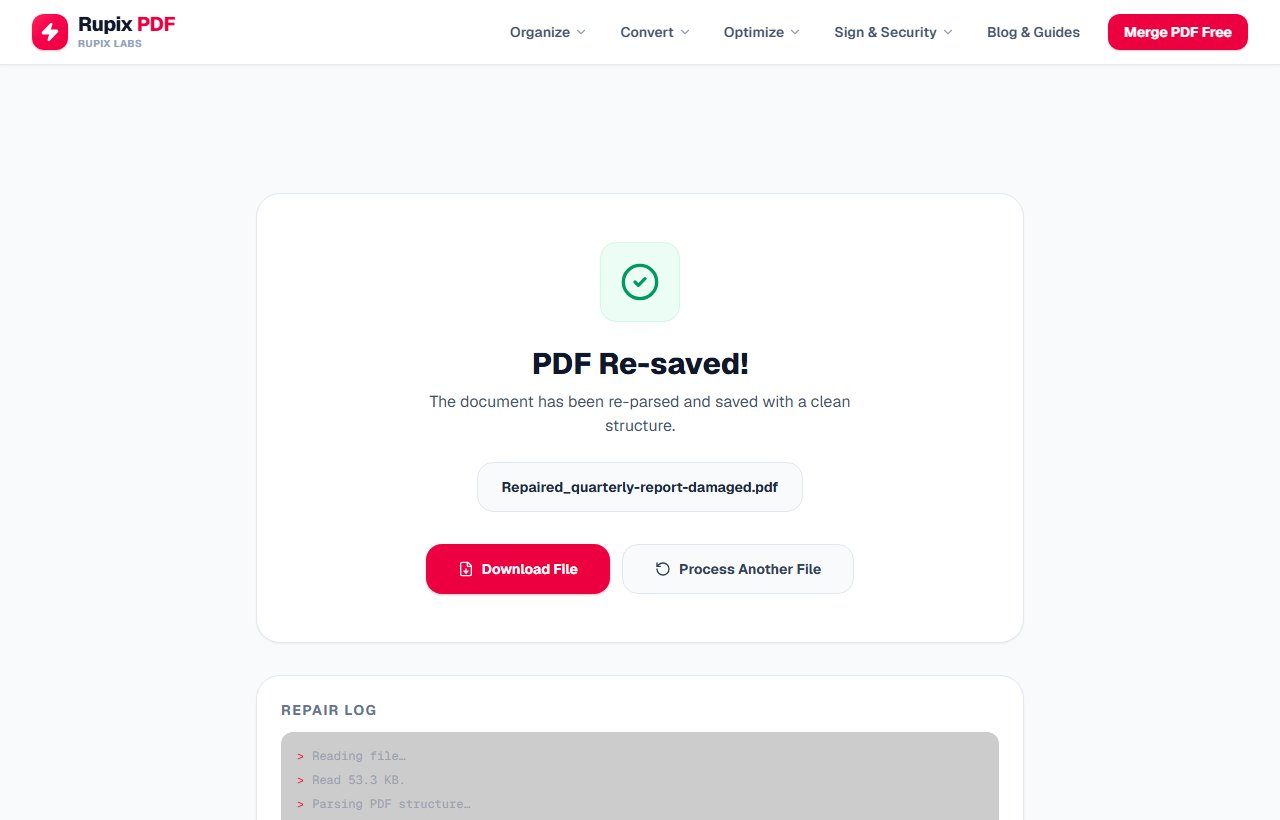
The PDF Re-saved! screen showing Repaired_quarterly-report-damaged.pdf with the Download File and Process Another File buttons, and the repair log below. - 5
Check the result, or accept an honest failure
Open the repaired copy and go through every page to confirm the content is there. If instead an alert says "This PDF couldn't be parsed — it may be too damaged for an in-browser re-save to recover" and the log ends with Stopped, the damage is more than a re-save can fix; look for another copy in the original email, your cloud storage or backups, or ask the sender again. Trying the same file again will give the same result.
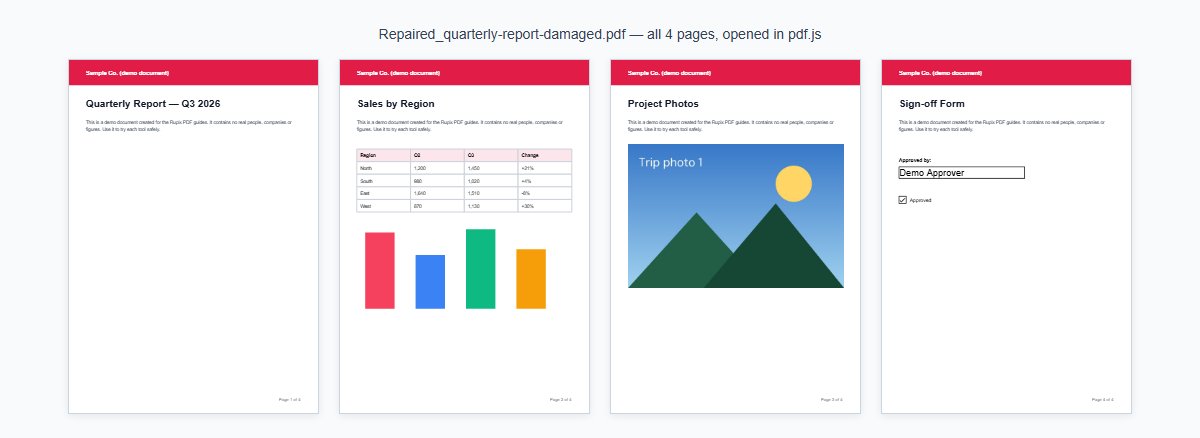
All four pages of Repaired_quarterly-report-damaged.pdf opened in PDF.js after the repair.
100% Client-Side Privacy Guarantee
Unlike other online PDF converters, Rupix operates on a zero-upload architecture. All PDF processing occurs locally in your browser memory using WebAssembly. No document bytes are ever uploaded to any server.
Engine Specifications
Supported Input
Corrupted, Damaged, or Truncated PDF
Output Format
Rebuilt Standard PDF (.pdf), named Repaired_ plus original name
Engine
pdf-lib (Resilient Parser)
Recovery Actions
XREF Rebuilding, Object Table Reconstruction
Privacy
100% In-Browser Execution
File Limit
Up to 100 MB per file
Why use Rupix Repair PDF?
Performs a structural re-save: reads the file object by object with pdf-lib, writes a new file with a correct cross-reference table
Fixes PDFs with missing or broken XREF tables, missing trailers, or missing end-of-file markers
Does not re-render pages — text stays selectable, images keep their resolution
Progress bar and log show real steps: file size read, pages and objects parsed, rewritten file size
Result screen reads "PDF Re-saved!" with the full repair log
Cannot recreate missing or overwritten content (file cut off halfway = not repairable)
100% client-side processing with pdf-lib, no uploads
Free, no sign-up, files up to 100 MB
Frequently Asked Questions
How do I repair a broken PDF that won't open?
Load it here and click Repair Document. If the pages are still inside the file and only its index or ending is damaged, you get a Repaired_ copy that normal readers can open; in our test, a file PDF.js rejected as "Invalid PDF structure" came back with all 4 pages. If the tool says the PDF couldn't be parsed, the damage is beyond a re-save and you need another copy of the file.
What kinds of damage can a structural re-save fix?
Problems with the file's index rather than its content: a missing or wrong cross-reference table, a missing or broken trailer, a missing end-of-file marker, or leftovers from an app that crashed while saving. Readers rely on that index to find pages, so rebuilding it often turns a file that refused to open into one that opens normally.
My file still will not open after repair. What now?
If the tool reported that the file couldn't be parsed, real content is missing or overwritten, for example because the file was cut off halfway, as in our test. No software can recreate bytes that are not there. Retrieve the original email attachment, check cloud or backup versions, or ask the sender to send it again and compare the file sizes.
Is there a file size or page limit for repair?
The upload panel accepts files up to 100 MB and there is no page limit. The whole document is held in memory while it is read and rewritten, so very large scanned files work best on a device with plenty of RAM. Keep the tab open until the result or error appears.
Should I run a digitally signed PDF through repair?
Only if the file is already broken. Re-saving rewrites the file, so signature checks will report the document as modified even when every page looks the same. If the signed original opens, leave it alone; if it is damaged, repair a copy and expect the signature to show as broken.