PDF to Word
Turn your PDF documents into editable Word (.docx) files. The text structure is reconstructed to match the original document.
Choose files
or drag and drop them here
What PDF to Word conversion does, and how editable the result really is
The PDF to Word tool reads the text layer of your PDF with PDF.js and writes it into a .docx file. Pieces of text that sit on the same baseline are joined into one line, and every line becomes its own paragraph in plain 12-point text. Each PDF page becomes a separate section, so page 2 of the PDF starts on a new page in Word. The document is A4 with 1-inch margins and downloads under the PDF's name with a .docx extension. Everything happens in your browser; the file is not uploaded.
"Editable" here means every word you can see is real, typeable text. It does not mean the layout comes back. We converted a 4-page demo report (50.9 KB) and got an 8.9 KB .docx in about a tenth of a second. The title came back at the same 12-point size as the body text. The 5-row table came back as five lines of text, such as "North 1,200 1,450 +21%", with spaces where the cell borders were. A paragraph that wrapped onto two lines in the PDF became two separate paragraphs. The photo on page 3 and the name typed into a form field on page 4 were not in the Word file at all, and the "Page 2 of 4" footers became ordinary paragraphs.
That makes the tool good for getting text out of a PDF so you can rewrite, quote or reuse it, and a poor choice when you need the document to look the same. It needs a PDF with real text in it. A scanned page is only a picture: our image-only test page produced a .docx with no paragraphs at all, so run scans through OCR software first. Two-column layouts also need care. In our two-column test, each line of the left column was joined to the line beside it in the right column, so the columns were mixed together line by line.
How to convert a PDF to an editable Word document
The conversion itself is one click. Most of your time goes into the last step: tidying the text in Word.
- 1
Open the tool and choose your PDF
Go to pdf.rupix.io/pdf-to-word. Click Choose Files, or drag a PDF onto the dashed box. The box is headed "Choose PDF files", but the tool takes one PDF at a time, up to 100 MB. Pick a PDF that was saved from a program, not a scan, because the tool can only read text that is already in the file.
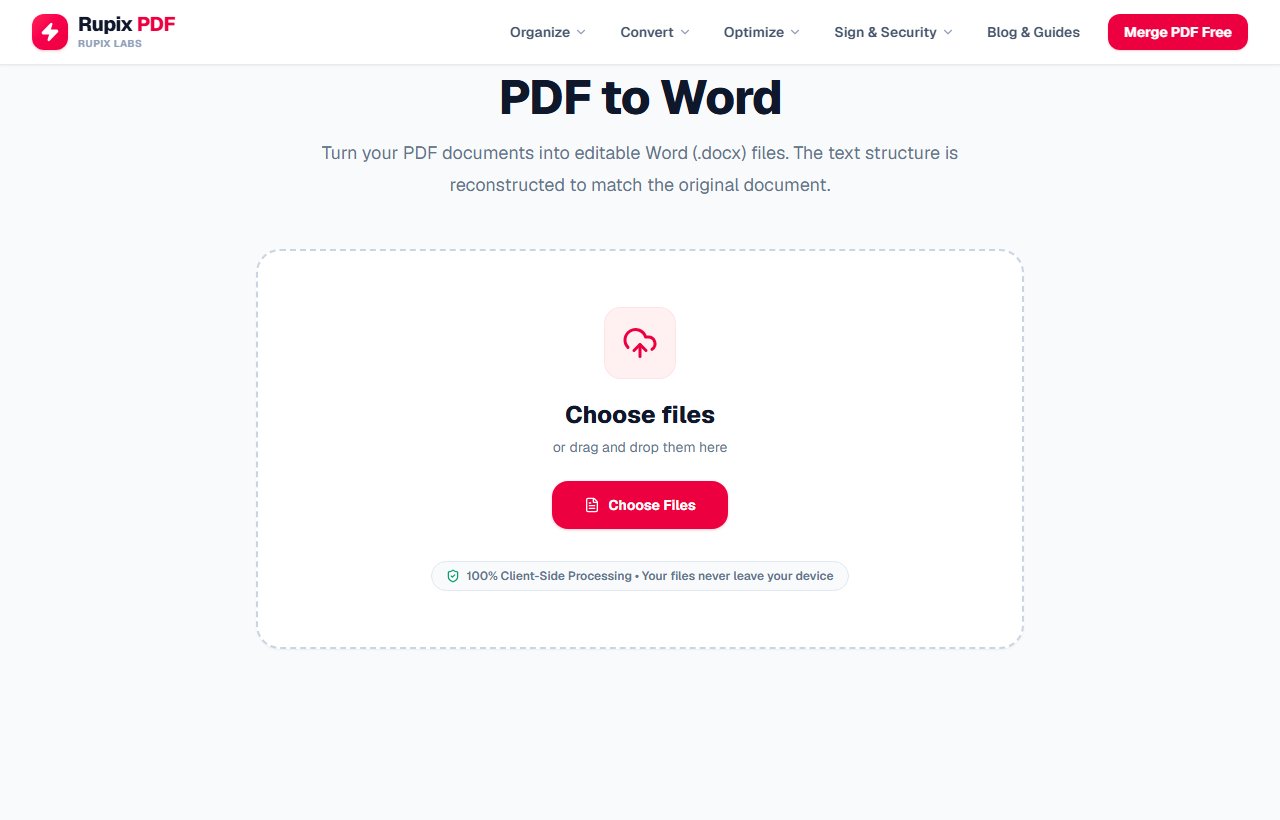
The PDF to Word page with the dashed upload box, the Choose Files button and the note that files stay on your device. - 2
Check the file card
The file appears in a card with its name and size; ours showed sample-report.pdf at 50.86 KB. Press the X on the right if you picked the wrong file. The two panels underneath, Text Reconstruction and Full Editability, are descriptions only. There are no settings to choose.
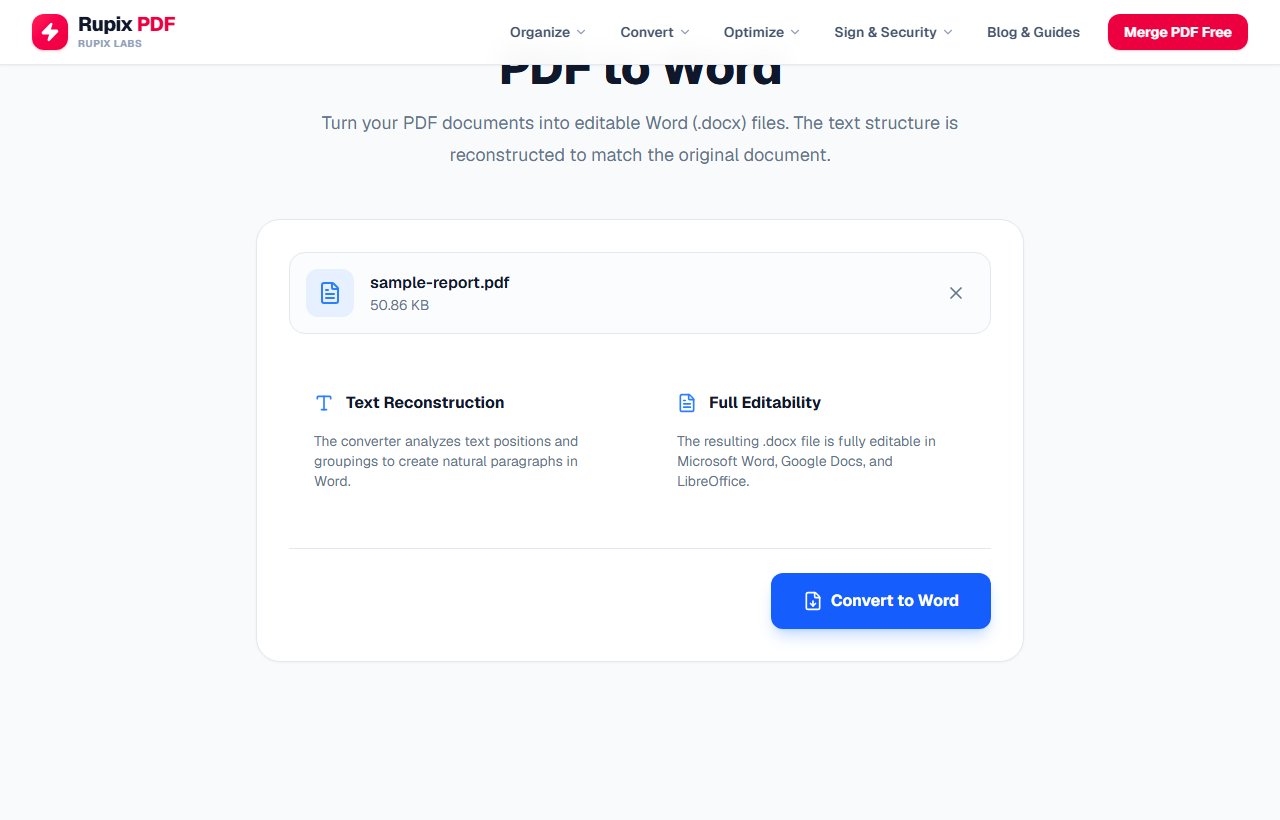
The card for sample-report.pdf (50.86 KB) above the Text Reconstruction and Full Editability panels, with the blue Convert to Word button. - 3
Click Convert to Word
Press the blue Convert to Word button. It changes to "Converting..." while the pages are read. Our 4-page file finished in about 0.1 seconds, so on most computers you will barely see this state before the download starts.
The button in its faded "Converting..." state. We slowed the browser down to capture it; normally it lasts a fraction of a second. - 4
Save the .docx
The "Conversion Complete!" screen shows the output name, here sample-report.docx, and the download starts by itself. If your browser blocked it, press Download File. Process Another File takes you back to the upload box.
The Conversion Complete! screen showing sample-report.docx with the Download File and Process Another File buttons. - 5
Tidy the text in Word
Open the file in Word, Google Docs or LibreOffice. Apply heading styles to the titles, since everything arrives as 12-point body text. Delete repeated page headers and footers, and re-insert any images you need from the original. To rebuild a table, first check what separates the values. In our test the cells were separated by three spaces. If yours are too, use Find and Replace to change three spaces into a tab, then select the lines and use Convert Text to Table with tabs as the separator.
100% Client-Side Privacy Guarantee
Unlike other online PDF converters, Rupix operates on a zero-upload architecture. All PDF processing occurs locally in your browser memory using WebAssembly. No document bytes are ever uploaded to any server.
Engine Specifications
Supported Input
Standard PDF (.pdf)
Output Format
Microsoft Word Document (.docx)
Text Extraction
Mozilla PDF.js TextContent Engine
Docx Packaging
docx.js Packer (Client-Side)
Privacy
100% In-Browser Execution
Compatibility
Word 2007+, Office 365, Google Docs
Max File Size
Up to 100 MB per file
Why use Rupix PDF to Word Converter?
Converts PDF text layer into a .docx file with plain 12-pt paragraphs
Each PDF page becomes a separate section (page break) in Word
Tables are converted to lines of text (cell values separated by spaces)
Images, fonts, colors, and layout formatting are not preserved
100% client-side conversion via PDF.js text extraction and docx.js packaging
Zero server uploads — complete security for legal briefs and personal resumes
Fully compatible with Microsoft Word, Google Docs, and LibreOffice
Free, no sign-up, files up to 100 MB
Frequently Asked Questions
Can I convert a PDF to an editable Word document online without uploading it?
Yes. The PDF is read and the .docx is built inside your browser tab, and nothing is sent to a server. The words in the result are fully editable, but the formatting is not rebuilt: headings, fonts, colours, tables and images do not carry over. You get the text, in page order, ready to edit.
Why did my table turn into lines of text?
The converter only writes paragraphs, never Word tables. Each row of a PDF table becomes one line with the cell values separated by spaces. In our test, a 4-column table row came out as "North 1,200 1,450 +21%". If you need the table as cells, the PDF to Excel tool keeps each value in its own cell, or you can convert the text to a table in Word as described in the last step above.
Why is my Word file empty?
Your PDF is almost certainly a scan or a photo. A scanned page has no text layer to read, so nothing is extracted. Our image-only test page produced a .docx with zero paragraphs. Run the file through OCR software first so it gains a text layer, then convert it here.
What happens to images, fonts and filled-in form fields?
They are dropped. The output contains text only, all in the same 12-point default font. In our test, the photo on one page and the value typed into a form field on another were missing from the Word file. Printed labels next to form fields do come through, because they are part of the page text.
How does a two-column PDF come out?
Badly, without cleanup. Lines are grouped by their height on the page, so a line in the left column and the line level with it in the right column end up in the same paragraph. In our test every paragraph read "Left column line one Right column line one", and so on down the page. For newsletters or academic papers, expect to separate the columns by hand.