PDF to Excel
Extract tabular data from PDF files and convert it to editable Excel (.xlsx) spreadsheets. Uses spatial analysis to reconstruct rows and columns.
Choose files
or drag and drop them here
Getting a table out of a PDF and into Excel: what this tool does
PDF to Excel reads the text layer of every page and groups text that sits on the same line into one row. It splits a line into cells wherever there is a gap wider than about one letter's width, then lines the cells up into columns by looking at where the table's cells sit across the whole page. Every row goes into a single worksheet called Extracted Data, in page order. The tool copies all the text on each page, not only the tables. Titles, paragraphs and page footers each become rows too, usually in column A, and you delete the rows you do not need. The .xlsx file is built in your browser and downloads under the PDF's name.
We tested it on a 4-page demo report whose second page has a 5-row, 4-column table and a bar chart under it. The table came through cleanly: "Region, Q2, Q3, Change" and the four data rows landed in cells A10 to D14 of a 27-row sheet. Values that look like numbers are saved as numbers, so SUM works straight away: "1,200" became 1200 shown as 1,200, and "+21%" became 21% (0.21). The tool also understands ₹, Rs., $, € and £ in front of an amount, Indian grouping such as 12,50,000.00, minus signs and amounts in brackets like (4,500.00). Codes with leading zeros such as 007, dates, and numbers longer than 15 digits, like account numbers, stay as text. Amounts in Indian grouping keep their value but Excel shows them with its own comma grouping (1,250,000.00). The bar chart produced nothing, because its bars are coloured shapes with no numbers in the text layer.
On our statement-style test PDF, every value landed under its own heading. The date and description came out in separate columns, and so did the credit and balance amounts. On the opening-balance row, where only the balance is filled in, 10,000.00 landed in column E under Balance, with the Debit and Credit cells left empty. A description that wrapped onto a second line in the PDF comes out as a second row with just that text. Column widths are set from the longest text in each column. Scanned PDFs have no text layer, and our image-only test page gave an empty sheet. Column detection is based on layout alone, so still compare a few rows with the PDF before you rely on totals.
How to convert a PDF table to Excel
Extraction takes a fraction of a second. After the download, you find your table, delete the rows around it and check a few values.
- 1
Open the tool and choose your PDF
Go to pdf.rupix.io/pdf-to-excel and click Choose Files, or drag the PDF onto the dashed box. One PDF at a time, up to 100 MB. It has to be a PDF with real text in it, such as a downloaded statement or a report exported from a program. Try selecting a word in your PDF viewer first; if you can't select the text, this tool can't read it either.
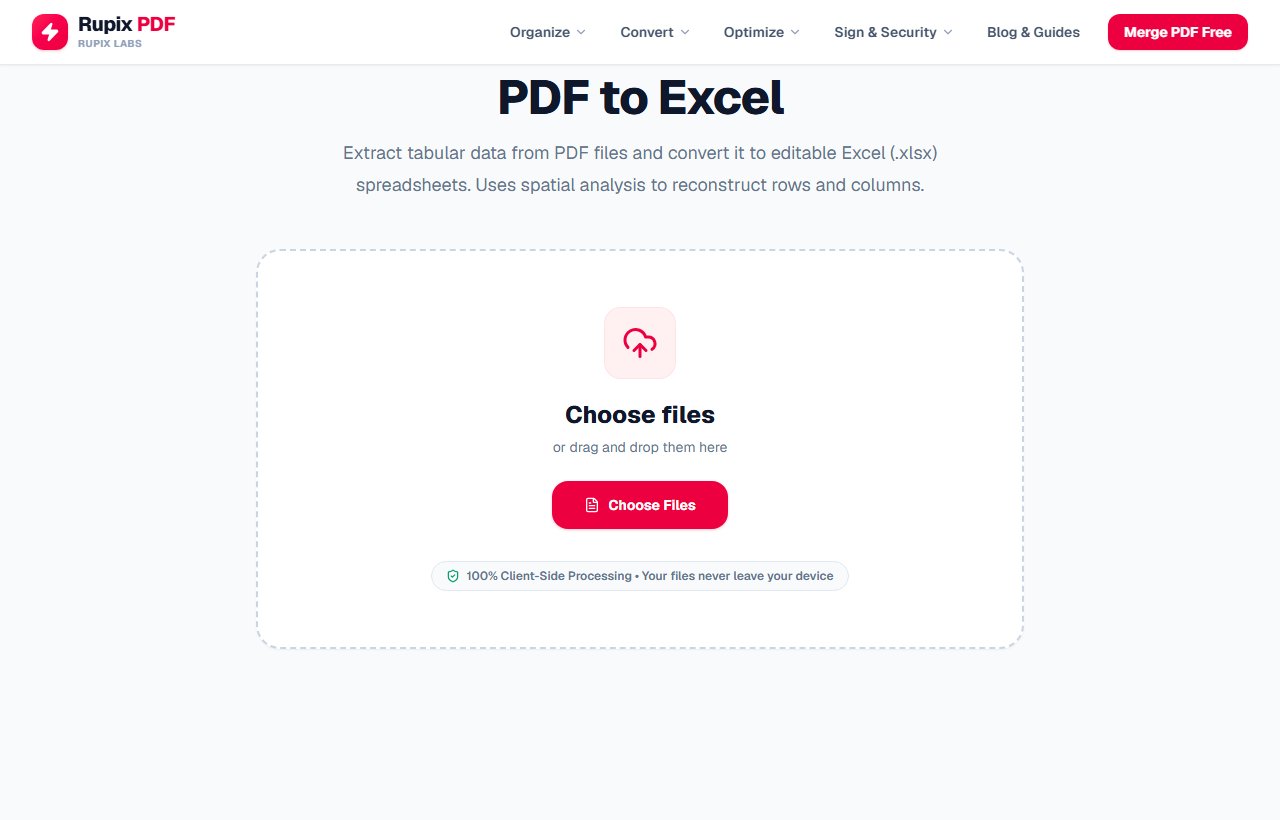
The PDF to Excel page with the dashed upload box and the Choose Files button. - 2
Check the file card
The PDF appears as a card with its name and size. Our demo report was 50.86 KB. Press the X to swap the file. The Column Detection and Excel Output panels below the card only describe the tool. There are no options: no page range and no choice of which table to extract.
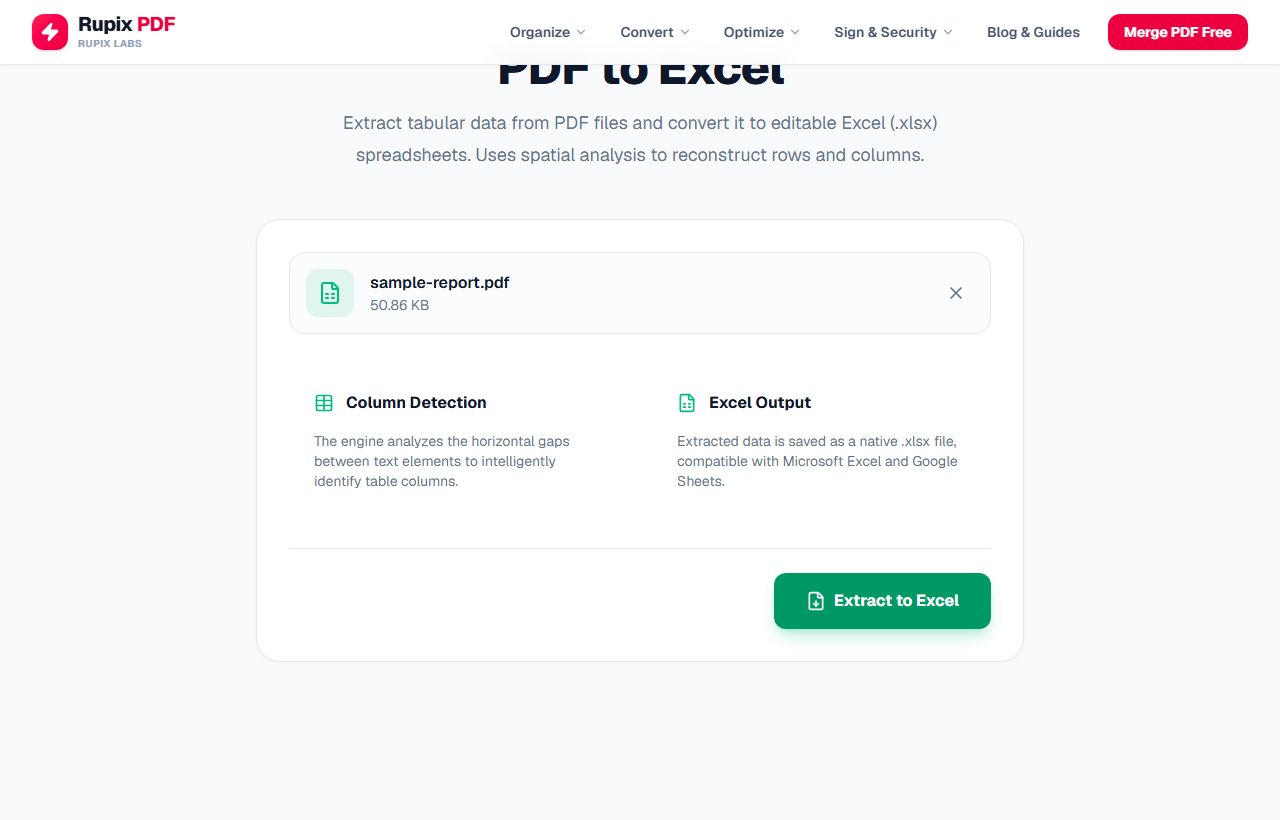
The card for sample-report.pdf with the Column Detection and Excel Output panels and the green Extract to Excel button. - 3
Click Extract to Excel
Press the green Extract to Excel button. It shows "Extracting..." while each page is read. Our 4-page report took about a third of a second, so the download usually starts almost at once.
The button in its faded "Extracting..." state. We slowed the browser down to capture it; normally it lasts a fraction of a second. - 4
Save the workbook
The "Extraction Complete!" screen shows the file name, here sample-report.xlsx, and the download starts automatically. Use Download File if it did not, or Process Another File to start again.
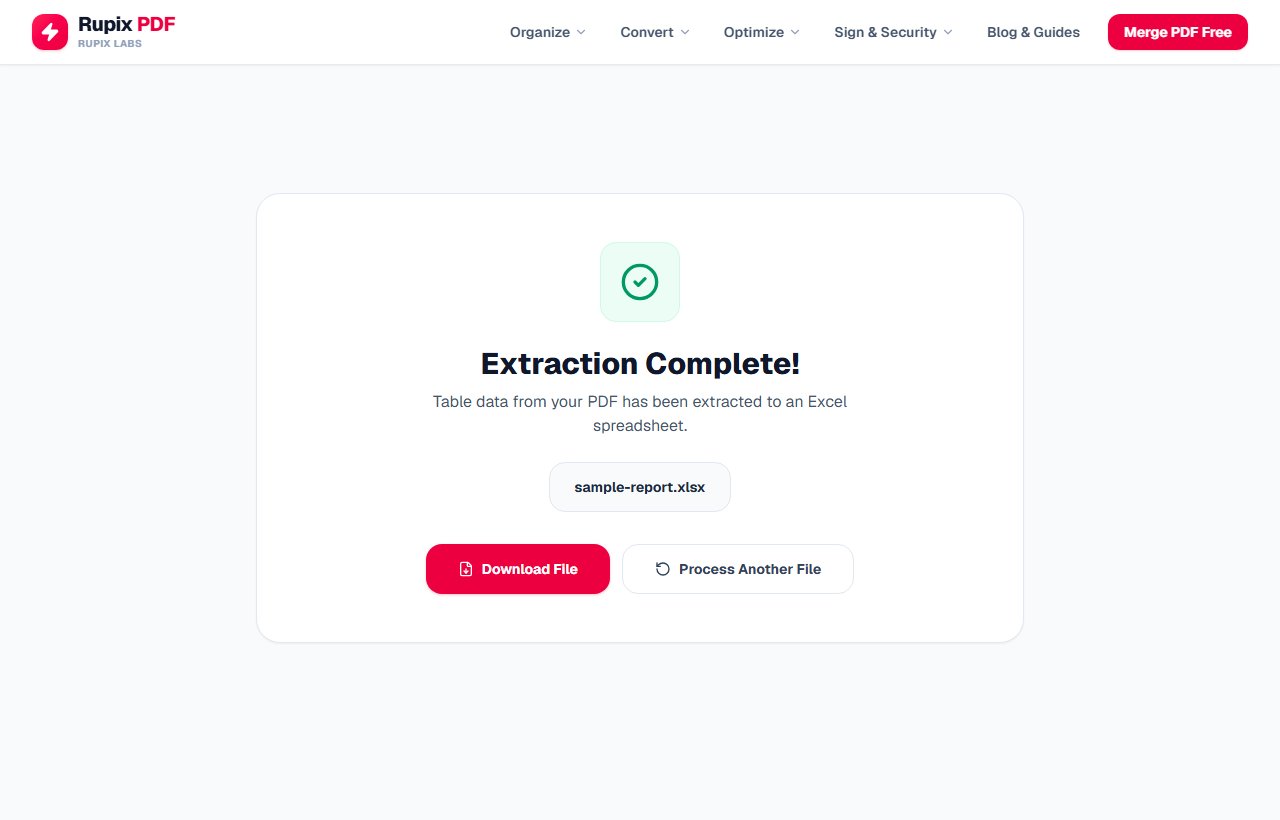
The Extraction Complete! screen showing sample-report.xlsx with Download File and Process Another File buttons. - 5
Find your table and delete the rest
Open the file in Excel, Google Sheets or LibreOffice. There is one sheet, Extracted Data, with every line of the PDF in page order. Scroll to your table and delete the rows above and below it. In our demo the table was in rows 10 to 14, surrounded by headings, body text and page footers.
- 6
Check the numbers and columns
Number cells are already real numbers, so formulas like SUM work. Compare a few rows with the PDF: make sure each value sits under the right heading, and that codes you want kept as text, such as invoice numbers, came through the way you expect. A wrapped description may need joining back onto the row above.
100% Client-Side Privacy Guarantee
Unlike other online PDF converters, Rupix operates on a zero-upload architecture. All PDF processing occurs locally in your browser memory using WebAssembly. No document bytes are ever uploaded to any server.
Engine Specifications
Supported Input
Vector/Text PDF (.pdf)
Output Format
Microsoft Excel OpenXML (.xlsx)
Extraction Engine
PDF.js (text coordinate analysis)
Workbook Generator
SheetJS (xlsx)
Privacy
100% Local On-Device Execution
Compatibility
Excel 2007+, Google Sheets, Numbers
File Limit
Up to 100 MB per file
Why use Rupix PDF to Excel Converter?
Reads text layer of every page and groups text on the same line into rows
Splits lines into cells at wide gaps; aligns columns across the whole page
Outputs a single worksheet "Extracted Data" with all page text in page order
Numbers (including ₹, Rs., $, €, £, brackets, Indian grouping) saved as real numbers — SUM works
Charts drawn as shapes are NOT extracted (no numbers in text layer)
No preview, no copy feature, no extraction mode — straight to .xlsx download
Button reads "Extract to Excel"
100% client-side via PDF.js and SheetJS, no uploads
Free, no sign-up, files up to 100 MB
Frequently Asked Questions
Can I convert a PDF table to Excel with this tool?
Yes, if the PDF has real text rather than a scanned image. In our test, a 5-row, 4-column table came out with every value in its own cell and the numbers stored as numbers. You also get every other line of text on the page as extra rows, so plan to delete those.
Can it turn a chart in a PDF into Excel data?
No. A chart in a PDF is usually drawn as shapes, such as bars, lines and slices, and those carry no numbers the tool can read. The bar chart in our test produced no rows at all. If the chart has values printed as labels, those labels come through as loose text that you would have to arrange yourself. To get the real data, find the table or spreadsheet the chart was made from.
Will SUM work on the extracted numbers?
Yes. Cells such as "1,200", "₹1,250.50", "(4,500.00)" and "+21%" are saved as numbers with a matching display format, so formulas work immediately. Text that only looks partly numeric, such as dates, codes with leading zeros like 007 and very long account numbers, stays as text on purpose.
What if a row has empty cells?
The tool works out each column's position from the whole page, so a value is placed under the heading it sits beneath, and an empty cell in the PDF stays empty in Excel. In our statement test, an opening balance with no debit or credit landed in the Balance column. Very irregular layouts can still confuse it, so check rows with blanks.
Does it work on a scanned bank statement?
No. A scan is a picture with no text layer, and our image-only test page produced an empty sheet. You would need to run the statement through OCR software first. Many banks also let you download statements as CSV or Excel, which is more accurate than any PDF extraction.