Extract Images
Find and save all embedded images from your PDF document. Perfect for repurposing visuals and assets.
Choose files
or drag and drop them here
What Extract Images does, and when it beats taking screenshots
Extract Images looks inside a PDF for the pictures stored in it and saves them as separate image files, instead of taking a screenshot of the page. It goes through every page, decodes each embedded picture at the pixel size it was stored at, and shows the results in a gallery with each image's dimensions and file size. You can save any image on its own or download them all.
People use it to get back pictures they no longer have as separate files: product photos from a supplier catalogue, photos from a report, or artwork from a design proof that arrived as a PDF. A screenshot only captures the page at screen resolution; an extracted image keeps the stored pixel size, so it stays sharp when enlarged. Every image is saved as a PNG, even if it was stored as a JPEG inside the PDF. In our test a 1200 × 800 photo stored as a 46,052-byte JPEG came out as a 153,078-byte PNG: the same pixels, about 3.3 times the file size.
The tool finds pictures wherever they appear: in our tests it found the single photo on page 3 of a 4-page report, both photos in a 2-page file with a different photo on each page, all nine photos in a 9-page photo PDF, and pictures with transparency, which keep their transparent areas in the PNG. A picture that appears on several pages is listed once. Only bitmap pictures are extracted; charts, icons and logos drawn as vector shapes have no image to pull out, and the bar chart in our sample report is an example. A phone photo that carries a rotation tag may come out turned upright rather than exactly as stored. Scanning happens entirely in your browser, and nothing is uploaded.
How to extract images from a PDF, step by step
One upload and one scan: any pictures the tool finds appear in a gallery ready to save. The example below uses a 4-page demo report with one photo on page 3.
- 1
Open the Extract Images tool
Open pdf.rupix.io/extract-images in any modern browser. The upload panel appears right away and the whole process runs locally. No account or plugin is needed.
The Extract Images page with its upload panel and Choose Files button. - 2
Load your PDF
Click Choose Files and pick a PDF of up to 100 MB, or drag it onto the panel. A card shows the file name and size above a Scan for Images button. This card has no remove button, so if you picked the wrong file, reload the page and choose again.
The loaded file card for sample-report.pdf (50.86 KB) with the Scan for Images button. - 3
Click Scan for Images
Click Scan for Images. The button changes to Extracting… while each page is read and its pictures are decoded in memory. Short files finish almost at once; long, image-heavy ones take longer.
The Scan for Images button showing its Extracting… state with a spinner. - 4
Browse the results gallery
Found pictures appear in a grid under a bar showing how many were found (for example Found 1 image) and the file name. Each card has a preview, the pixel dimensions (for example 1200 × 800) and the size of the PNG it will save.
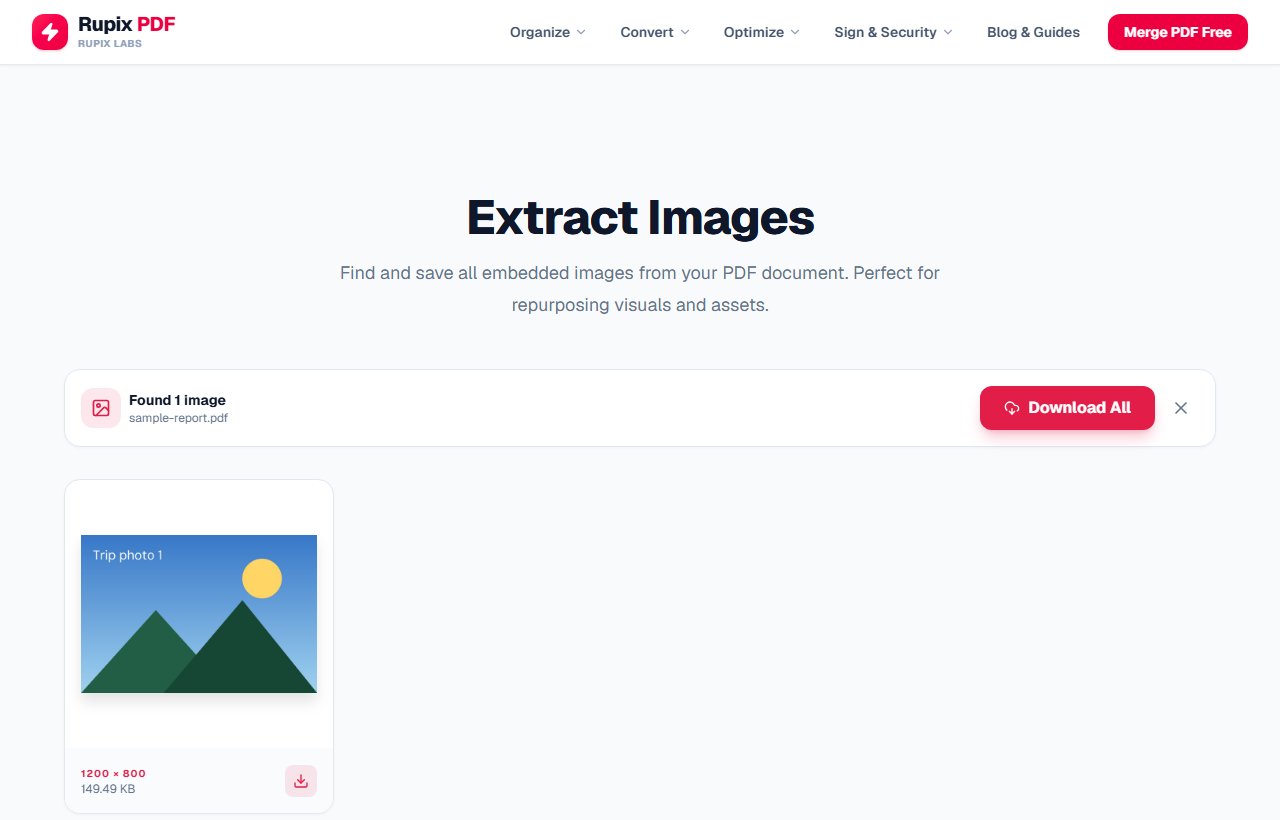
The gallery for sample-report.pdf: Found 1 image, one card showing a 1200 × 800 photo at 149.49 KB, with Download All at the top right. - 5
Download what you need
Click the download icon on a card to save that one image, or Download All to save every image one after another. Files are named extracted_page followed by the page number and the picture's position on that page, for example extracted_page3_1.png. Allow multiple downloads if your browser asks, and use the X in the top bar to clear the results.
The mouse over the download icon on the image card, next to the Download All button. - 6
If no images are found
If nothing is found, a browser alert says "No images found in this PDF." and, once you click OK, the page returns to the upload panel. It means the PDF contains only text and vector graphics, for example a document printed to PDF from a browser or word processor without photos. If you still need a picture of the page, PDF to JPG will give you each whole page as an image.
100% Client-Side Privacy Guarantee
Unlike other online PDF converters, Rupix operates on a zero-upload architecture. All PDF processing occurs locally in your browser memory using WebAssembly. No document bytes are ever uploaded to any server.
Engine Specifications
Supported Input
Standard PDF (.pdf)
Output Format
PNG (.png) only, saved as separate files
Extraction Engine
PDF.js (paintImageXObject hooks)
Privacy
100% On-Device In-Browser Execution
Max File Size
Up to 100 MB per file
Why use Rupix Extract Images from PDF?
Extract all embedded raster images and illustrations from any PDF
Each image is decoded at its stored pixel size and saved as PNG (even if originally JPEG)
Download extracted images individually or all at once as separate PNG files (no ZIP)
100% in-browser extraction using PDF.js; zero file uploads
Duplicate images (same image on multiple pages) are listed once
Vector graphics (charts, logos, diagrams) are not extracted — they have no image data
Free, no sign-up, files up to 100 MB
Frequently Asked Questions
Does this extract photos at original quality or take screenshots?
The tool decodes each picture to its pixels and saves those pixels as a PNG; it does not copy out the original JPEG data. PNG is lossless, so nothing is lost in that step, but photos take more space as PNG. In our test a 46,052-byte JPEG photo came out as a 153,078-byte PNG at the same 1200 × 800 size.
Why does it say "No images found" when my PDF clearly has photos?
Usually because what looks like a photo or graphic is not stored as a picture. Charts, logos and diagrams are often vector drawings, and some PDFs draw text and shapes only. In that case there is nothing to extract, and PDF to JPG is the way to save the page as an image. If a file you know contains photos still returns nothing, it may use an image format your browser cannot decode.
Does Download All bundle the images into a ZIP archive?
No. Download All saves each PNG as its own browser download, a fraction of a second apart. Your browser may ask for permission the first time a site downloads several files at once; allow it so all of them arrive.
Why was a chart, logo or icon skipped?
Many charts, logos and icons are drawn with vector shapes, not stored as pictures, so there is no image object to extract. The bar chart in our sample report is one of these. To capture such graphics, convert the page with PDF to JPG and crop the part you need.